Scientific compute for agents · API and MCP native
Unleash scientific tools for your agents.
Give your agents the power to do real science.
Your agent sends a prompt and the data. ScientistWorkbench runs the analysis in an isolated Linux sandbox with a curated life-science stack, an independent reviewer checks the report against what actually ran, and you get back a summary, figures, tables and the code.
No seats, no installs, no subscription required. One API key works for HTTP and MCP.
How it works
Submit
One prompt plus input files (xlsx, csv, fasta, PDFs …) over HTTP or an MCP tool call. Returns a job_id immediately.
Sandbox
A fresh Ubuntu sandbox per job with the full scientific stack below pre-installed and network access plus query guides for 24 life-science databases. Nothing shared between jobs or tenants.
Reviewed report
The agent writes summary.md (Objective · Method · Results · Assumptions · Files). A separate reviewer audits every claim against the execution log.
Collect
Summary, figures, tables, scripts, execution log and reviewer findings — as JSON, as files, or inline in your agent's context. Run hundreds in parallel.
Supercharge your agents with the power to do scientific analysis and access 24 life science databases
Every job starts in a fresh Ubuntu sandbox with this stack already installed, plus a skill that teaches the agent how to query each database directly (REST, with retries and a provenance log of every query). Package managers stay available, so anything else on PyPI or apt is one install away.
Compute stack
 SciPy
 pandas
 statsmodels
 scikit-learn
 matplotlib
 Biopython
 RDKit
| numerics & stats | numpy, SciPy, pandas, statsmodels, scikit-learn, pyarrow |
|---|---|
| figures | matplotlib, seaborn (publication-style defaults via the figure skill) |
| sequences & phylogenetics | Biopython, MAFFT, IQ-TREE, FastTree, HMMER |
| structure | TM-align, PDB/AlphaFold fetch helpers |
| chemistry | RDKit |
| files | openpyxl, xlrd, CSV/Parquet, PDF text extraction, LibreOffice headless |
| languages | Python 3 and shell; Node, Go, Rust, Java available |
24 life-science databases
Reachable from inside the sandbox, each with a skill page the agent reads before querying.
| proteins & genes | UniProt, Ensembl, InterPro, PDB, AlphaFold |
|---|---|
| variants & expression | gnomAD, ClinVar, dbSNP, GEO, GTEx |
| cancer & targets | DepMap, cBioPortal, Open Targets, Reactome |
| chemistry & drugs | PubChem, ChEMBL, BindingDB, openFDA |
| literature & trials | PubMed, Europe PMC, OpenAlex, bioRxiv, medRxiv, ClinicalTrials.gov |
What a job costs
Prepaid tokens, no seats. A job uses tokens in proportion to what it reads, computes and writes. Measured on the production engine:
| job | agent class | wall time | tokens |
|---|---|---|---|
| CRO assay QC Recompute plate statistics, refit IC50 curves, flag anomalies in a CRO xlsx deliverable | specialist | ≈ 11 min | 185k tokens |
| Database lookup One structured question against a public database (GTEx, UniProt, Open Targets, ChEMBL, DepMap, PubMed …), with a figure | lookup | ≈ 2 min | 58k tokens |
| Research phylogeny Family selection, MAFFT + FastTree, ancestral reconstruction, structural superposition, 5 figures | research | ≈ 39 min | 1.11M tokens |
Built for agent frameworks, not chat
API- and MCP-native
Nine MCP tools (science_submit, science_wait, science_result …) and a plain HTTP job API. Works from Claude Code, Claude Cowork, Cursor, Claude Desktop, the Agent SDK, or curl.
Durable job ids + provenance
Every artifact has a sha256 and a stable science:<job_id>/<file> ref. Transcript, execution log and reviewer record ship with every result.
Parallel by default
Submit and poll. Each job is its own sandbox; concurrency is a setting, not a queue you wait in.
Isolation
Per-job sandboxes, per-tenant storage keys, read-only mounted inputs, no shared state, no training on your data.
Real runs
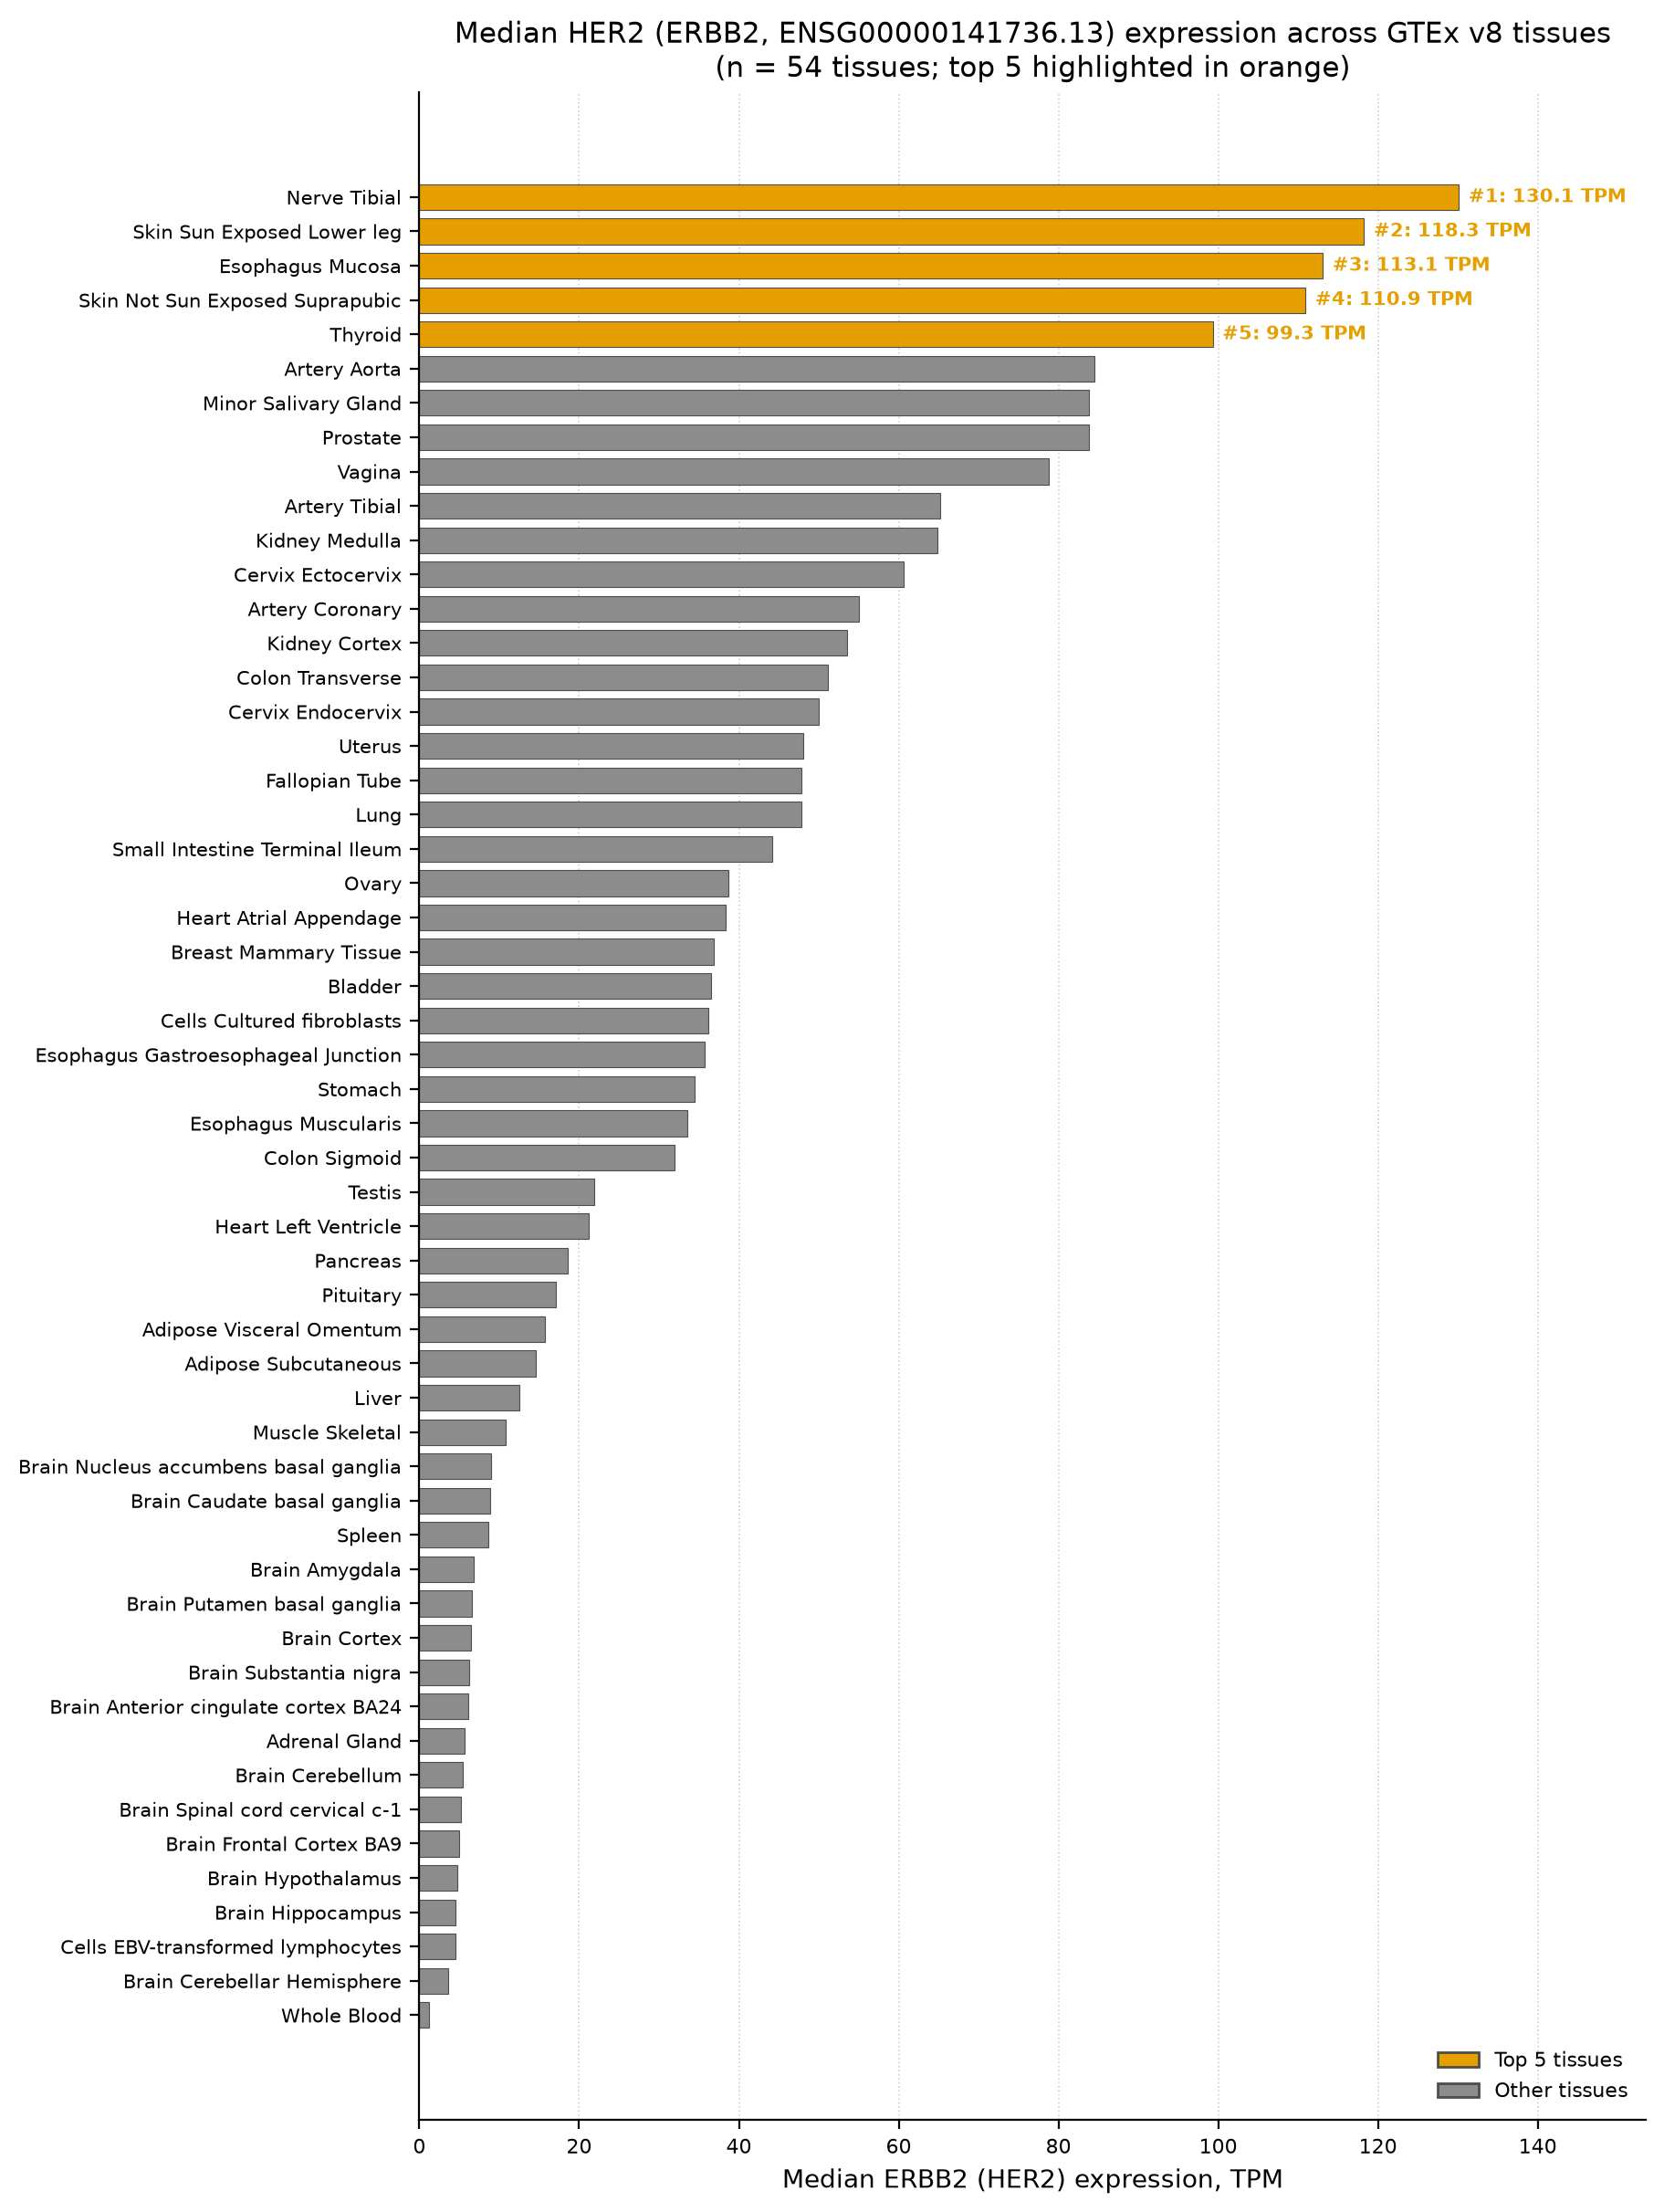
HER2 expression across GTEx tissues, live from the GTEx API
lookup · standard model · 2 min · 1 figure · 58k tokens
“Plot median expression of HER2 across GTEx tissues, highlight the top 5.”
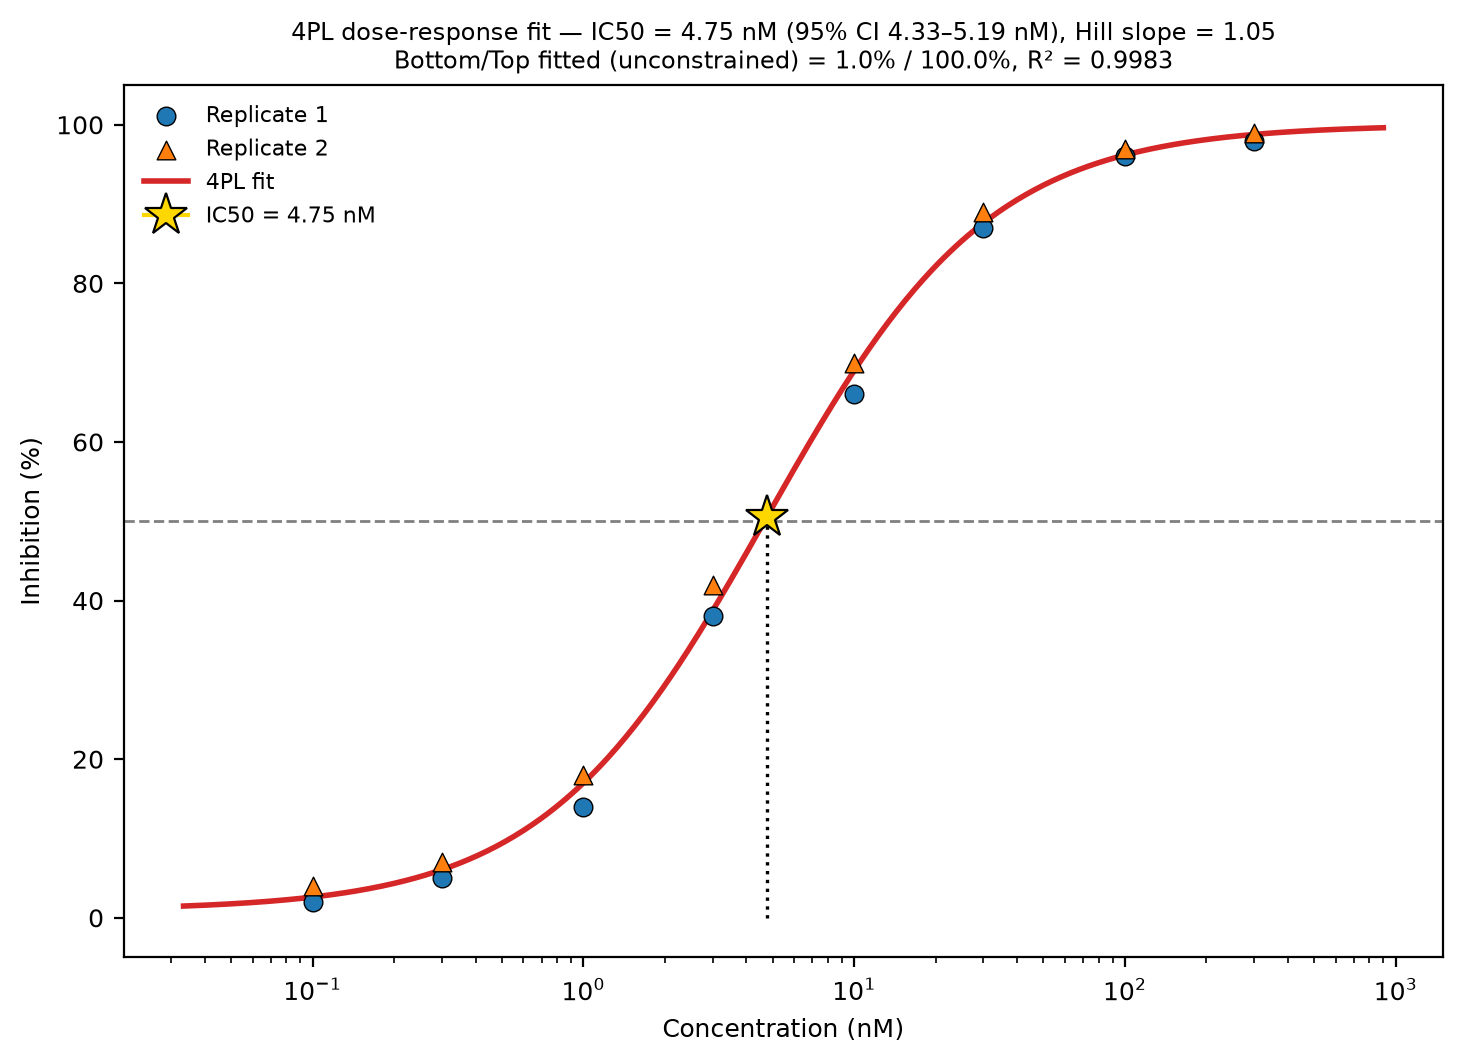
Dose-response fit from eight numbers in the prompt
specialist · standard model · 3 min · 1 figure · 59k tokens
“Fit a four-parameter logistic curve to this dose-response data (concentration in nM, % inhibition; duplicates): 0.1: 2, 4 · 0.3: 5, 7 · 1: 14, 18 · 3: 38, 42 · …”
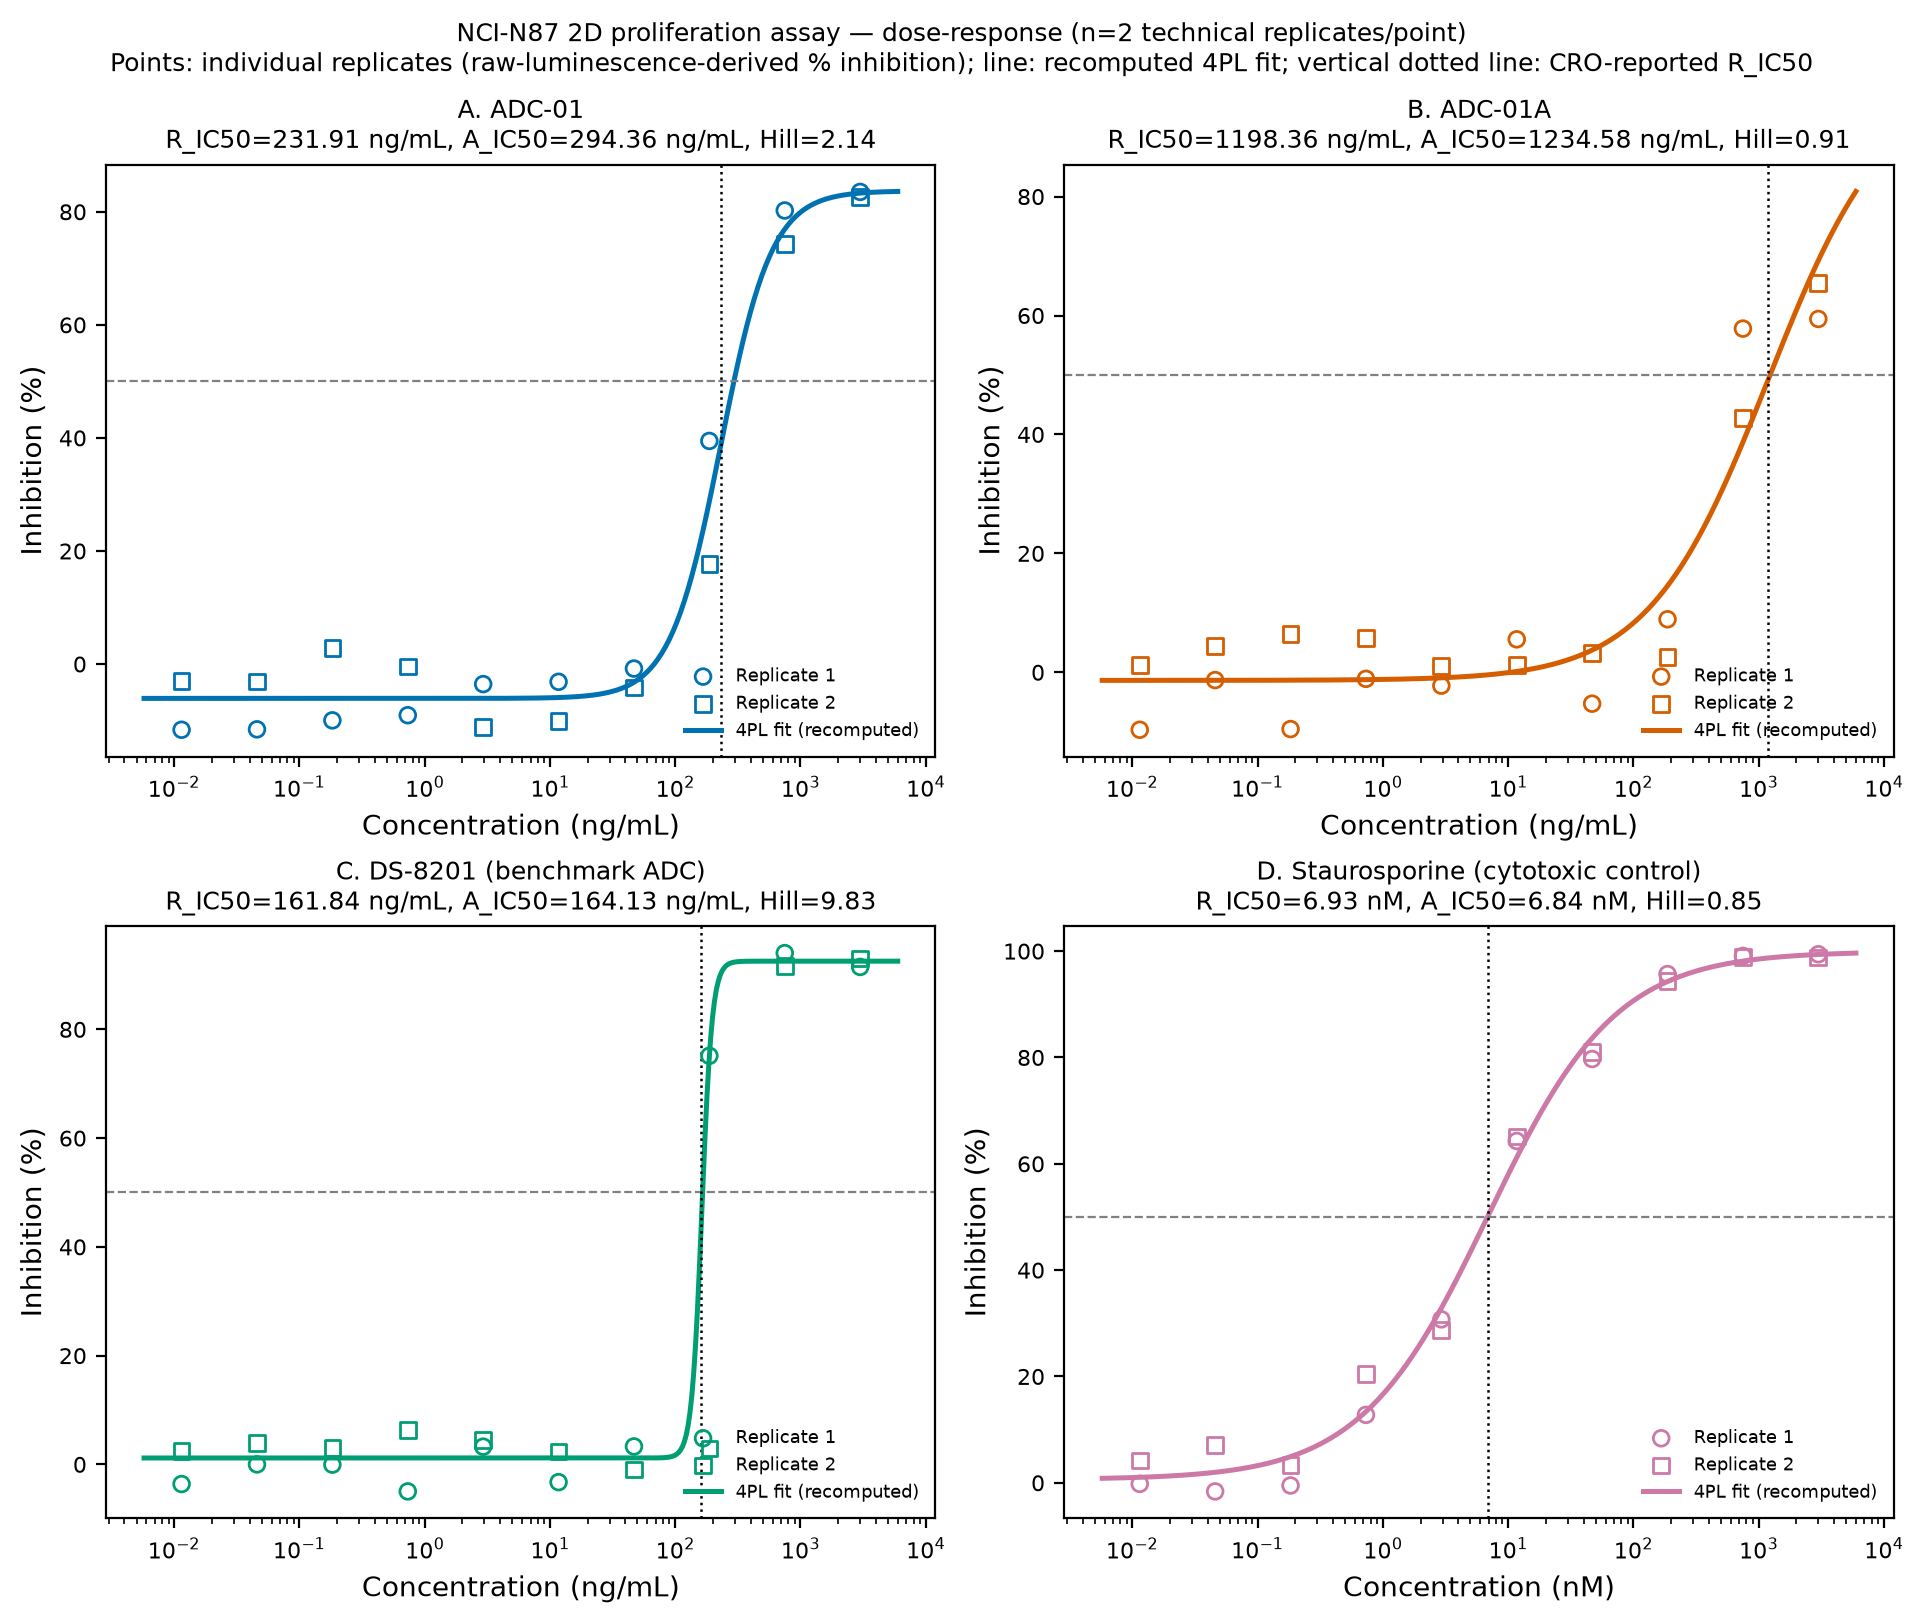
QC of a CRO IC50 deliverable (NCI-N87, two ADC candidates + benchmark + control)
specialist · standard model · 11 min · 2 figures · 173k tokens
“Take this data from the CRO and QC it and return a summary of the results.”
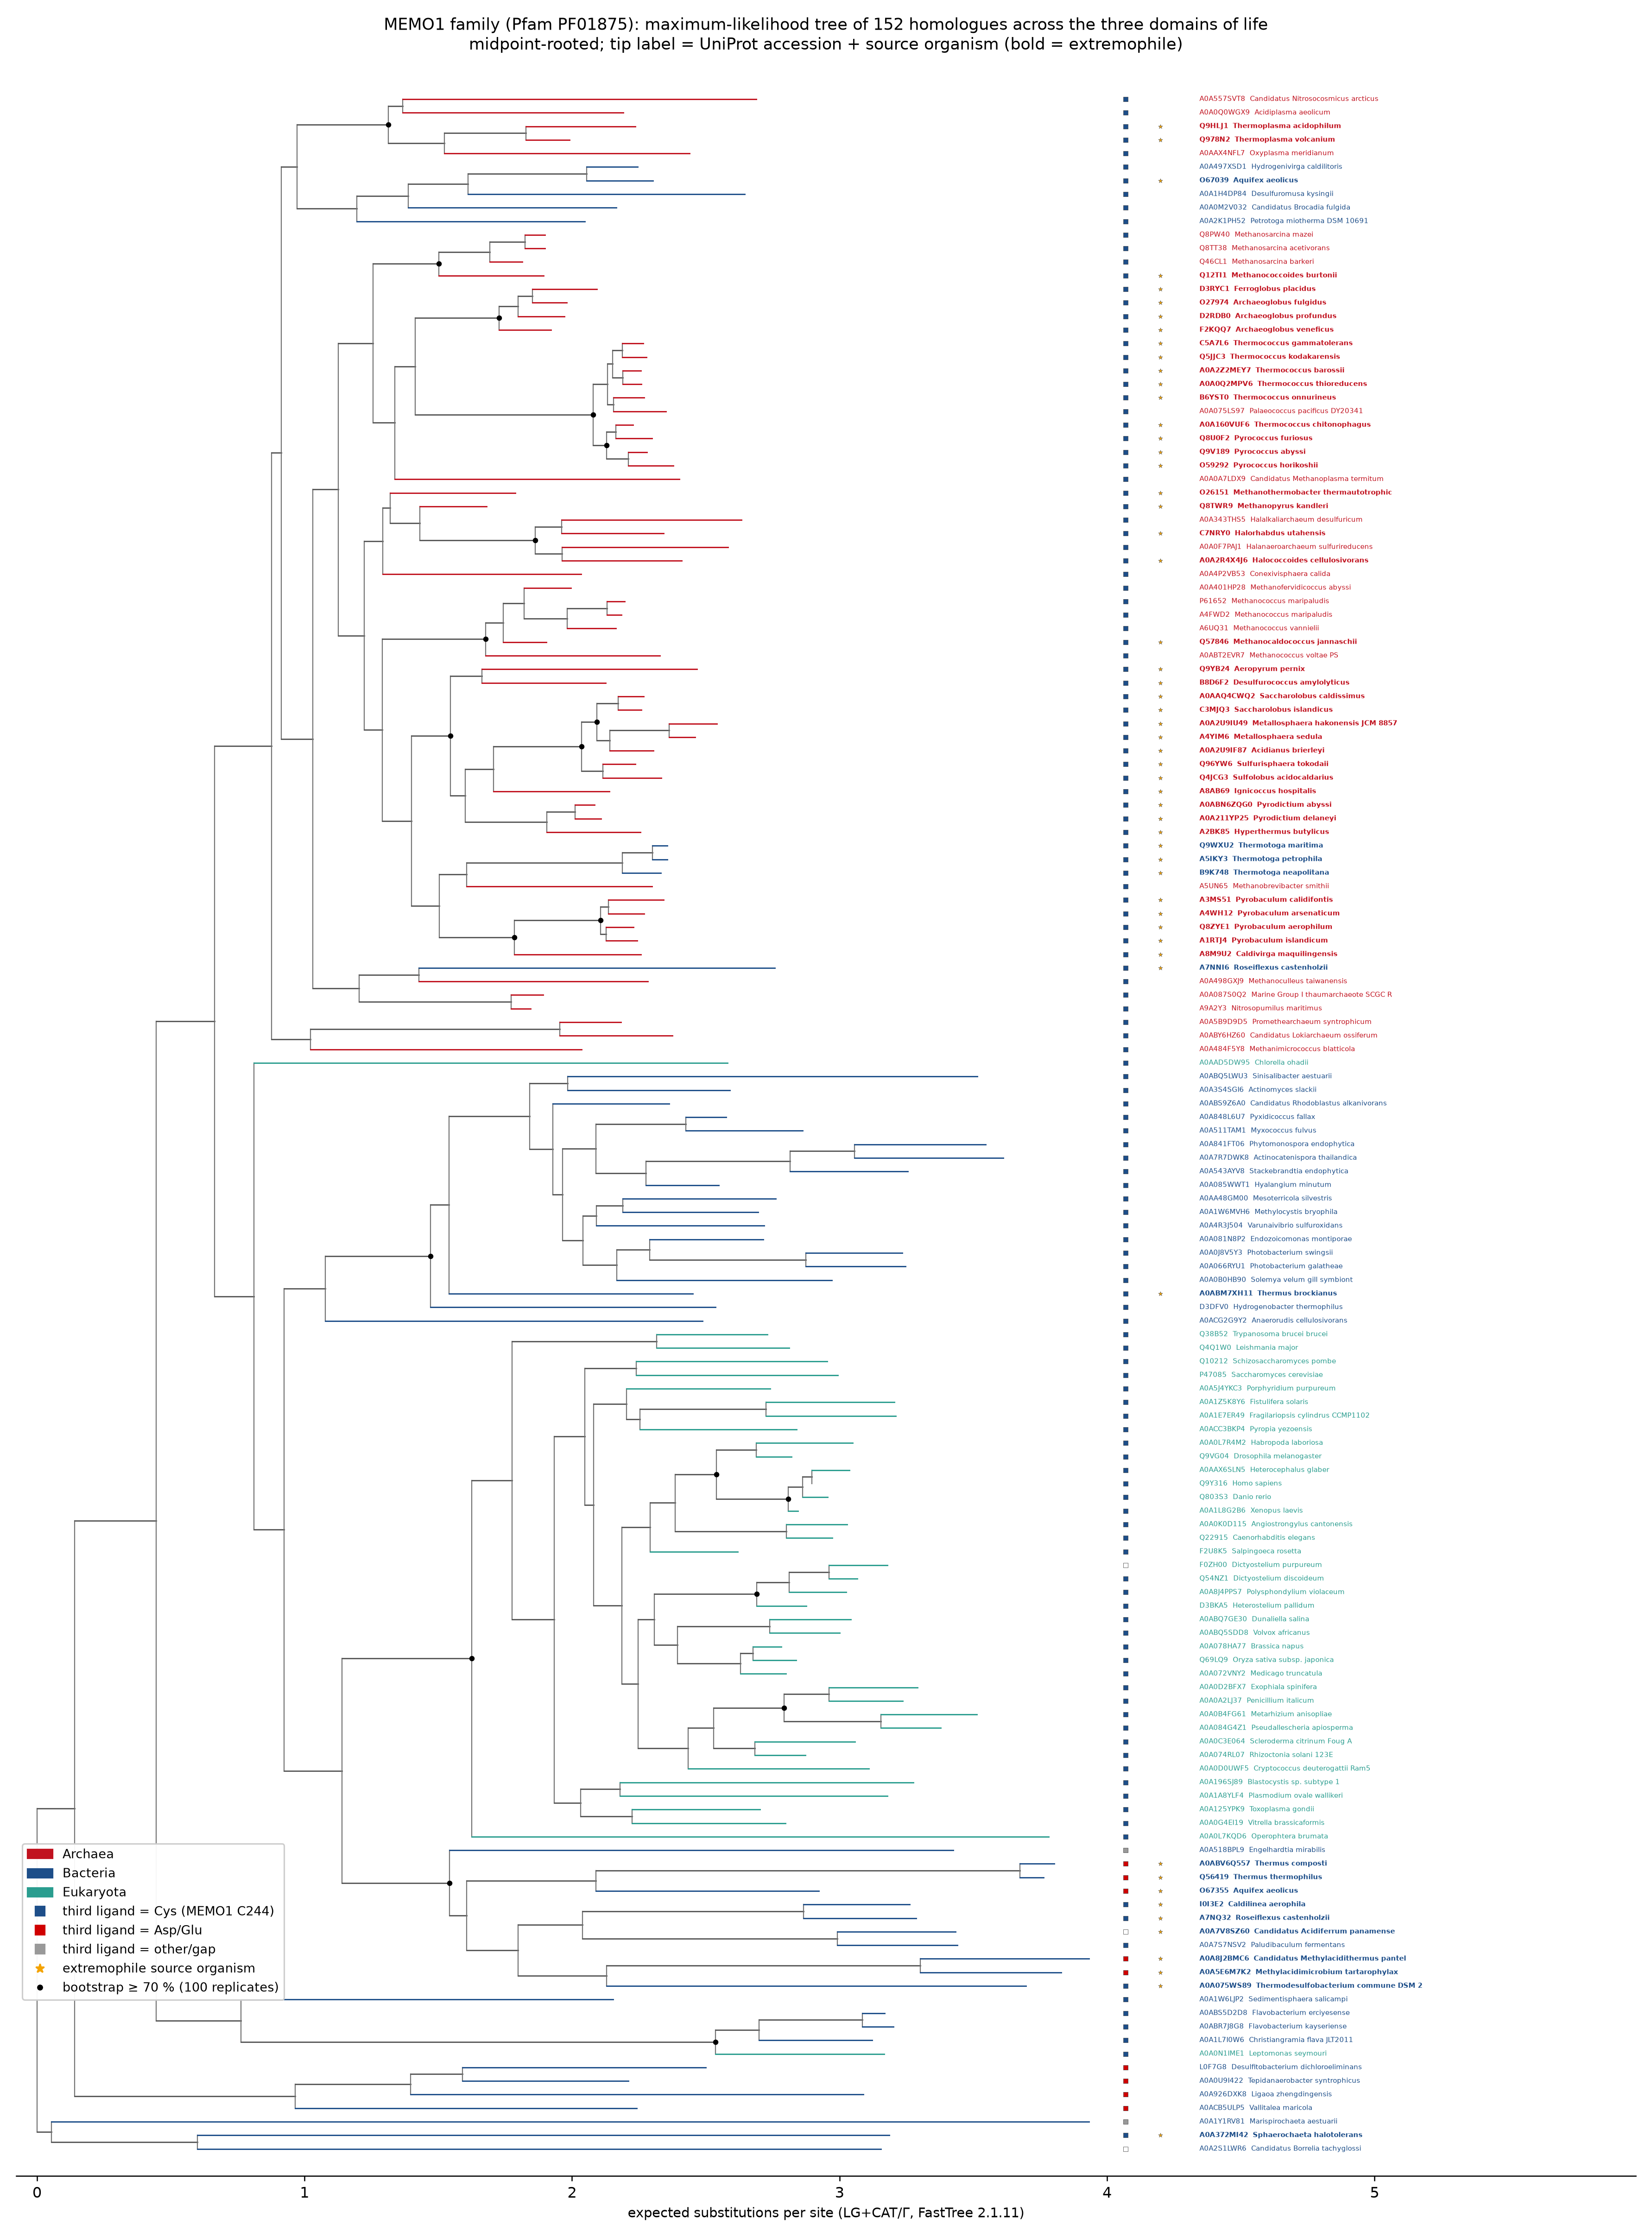
Proteins of unknown function in extremophiles: the MEMO1 family across the three domains of life
research · frontier model · 39 min · 5 figures · 1.11M tokens
“Give me an example of some proteins of unknown function in extremophiles. Choose the most interesting, and build a phylogenetic tree with related sequences acro…”
AI-generated analysis. Outputs may contain errors; verify numbers against the execution log and source files before relying on them. Not a substitute for review by a qualified scientist, and not medical advice: any use affecting patient care or healthcare decisions requires review by a qualified professional.